Applied Compute Raises $350M at $3.25B Valuation on $100M Annualized Revenue
AI infrastructure startup Applied Compute raised $350M at a $3.25B valuation, with annualized recurring revenue above $100M within 18 months of launch.
Applied Compute has raised $350 million at a $3.25 billion valuation, and the more telling number is the one it disclosed alongside the round: annualized recurring revenue above $100 million. For a company that launched less than 18 months ago, that's a fast climb. It also tells you that customers are paying for the product, not just testing it.
The round was led by angel investor Elad Gil, with participation from Nvidia, Shopify Ventures, HubSpot Ventures and more than a dozen other investors. Applied Compute counts Microsoft and DoorDash among its customers, along with other large tech firms. It plans to use the new capital to expand its market presence and buy more infrastructure.
What the platform actually does
Applied Compute runs a cloud platform where developers train large language models and serve them for inference, which is the step where a deployed model generates responses to user queries. That covers two parts of the lifecycle that often get handled by separate tools and separate teams. The company also employs machine learning researchers who work directly with customers, taking on tasks such as building quality evaluations for models that are still under development.
The interesting technical claim sits in the training stack. A typical LLM training setup has two main components. One spawns many copies of the model, assigns each a different task and converts the outputs into training data. The other takes that data and updates the model's weights. In most setups these run synchronously, so each waits for the other to finish before starting its next step. Idle time piles up quickly at scale.
Applied Compute uses asynchronous reinforcement learning instead, so data generation and weight updates run at the same time. The company says this speeds up development. It also supports self-distillation, which removes the need for teacher models, the specialized networks researchers often use to supervise a training run. If that holds up in practice, it means fewer moving parts and less dependence on a second model that has to be trained or licensed first.
Tooling around the training loop
The platform includes a built-in AI assistant aimed at a particular pain point. After a training run, researchers typically have to read through long reasoning logs to figure out what new skills the model picked up. The assistant can summarize those changes directly. That sounds minor, but anyone who has spent a day scrolling through logs will recognize the time it saves.
On the inference side, an autoscaling engine adjusts how much hardware a model gets based on incoming traffic. The company also offers what it calls online RL, which uses the prompts a deployed model receives to update its weights periodically. The goal is to keep the model aligned with what the customer needs as usage shifts. This is an unusual design choice. Most production systems freeze the model between training cycles, so continuous adaptation from live traffic raises questions about evaluation, drift and rollback that the company will need to answer for customers who run it at scale.
Applied Compute pairs these capabilities with a model router called Shift-1. It's built for coding agents and sends each user request to whichever LLM can handle it most cheaply. It can also split a complex task across several models. Routing has become a common pattern as teams realize that a single frontier model is often overkill for routine steps. The hard part is making routing decisions reliably, and that's where the value of a router depends on its accuracy, not just its cost savings.
Why the revenue figure matters more than the valuation
Valuations in AI infrastructure tend to run ahead of revenue, so the $3.25 billion figure on its own doesn't say much about the business. Annualized recurring revenue is a more concrete signal. It suggests recurring contracts or usage, rather than one-off pilots. Reaching $100 million in that metric within roughly a year and a half is rare, and it implies that the company's training and inference tools are being used for production workloads, not just experiments.
Still, the number has limits. Recurring revenue doesn't show margins, and infrastructure businesses can carry heavy compute costs that squeeze profitability. A company selling training and inference capacity also depends on hardware supply and pricing it doesn't control. The participation of Nvidia in the round is a reminder of how tightly the stack is tied to GPU availability, even though the investment itself doesn't tell you much about margins or contract terms.
What to watch next
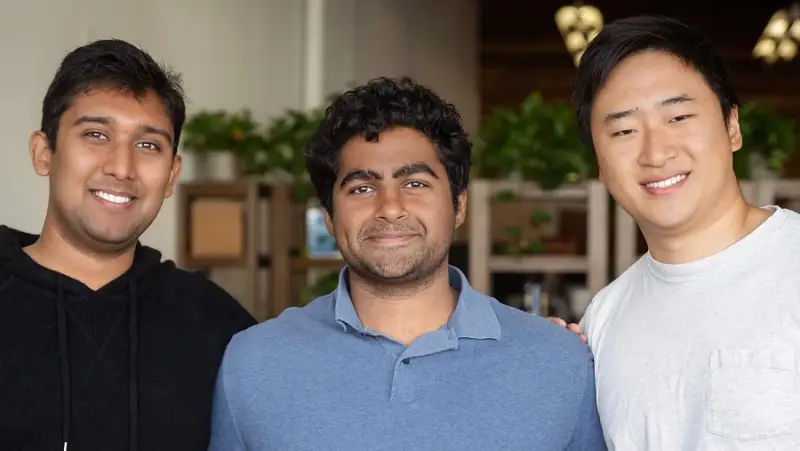
The company describes its current products as the first pieces of a larger stack. In a blog post, founders Rhythm Garg, Yash Patil and Linden Li wrote that they're "building the AI infrastructure every company will need to fully own their intelligence, from the models themselves to the systems that run, monitor and secure them." That's an ambitious scope, and it moves Applied Compute from a training and serving provider toward a broader operations layer for custom models.
The useful test over the next year will be whether asynchronous RL and self-distillation show up as measurable gains for customers, such as shorter training cycles or lower cost per useful model, rather than as architectural features. Teams evaluating the platform should ask for benchmark comparisons on their own workloads, look closely at how online RL handles model regression, and check how the router performs when tasks are ambiguous. If Applied Compute can show those results, the $100 million revenue figure will look like an early indicator rather than a peak.


